
-
Plum X and SSRN

This week we’re focusing on our brilliant research metrics partner, PlumX Metrics. PlumX is an extremely helpful tool that provides in-depth usage analytics on the research on SSRN. Plum takes a deeper dive into numbers such as social media usage, and gives you more insight into who’s citing a paper, for example, and what kind of social media buzz that it’s generating.
There are five categories of metrics that together make up PlumX, and all of them analyse scholarly research output for information that academics and researchers might find useful. We’ve listed the five categories below and explained what each of them might be able to show you:
- Citations: This category tells you about traditional citation indexes such as Scopus, but also citations that might indicate Clinical and Policy impact.
- Usage: This simply tells you how many people are reading, downloading or viewing your research on SSRN. Bear in mind this may slightly vary from the current numbers on the main SSRN display because of when the Plum X data feed is updated, so don’t sweat if you see small variances to the official SSRN number.
- Captures: This metric will tell you how many people have saved your research in some way so they come back to it later.
- Mentions: This category lets you know whether anyone has mentioned your research in a news article or blog post, outside social media. This can let you know if people are engaging with your research outside of traditional academic citations.
- Social Media: This key category tells you if people are Tweeting about the research or posting it on Facebook etc, and if there’s any ‘buzz’ about it.
On SSRN, there’s a helpful tool on every article page which tells us all about these five metrics. The tool is shown through a PlumX widget, that brightly coloured icon to the right:

You can see more information about what the different circles mean by hovering over the symbol with your mouse. This paper has garnered lots of attentions, so there’s a lot for Plum Metrics to share about it:

Finally, if you want to know more specific information such as who has Tweeted the paper, you can click on the symbol to show even more detail:
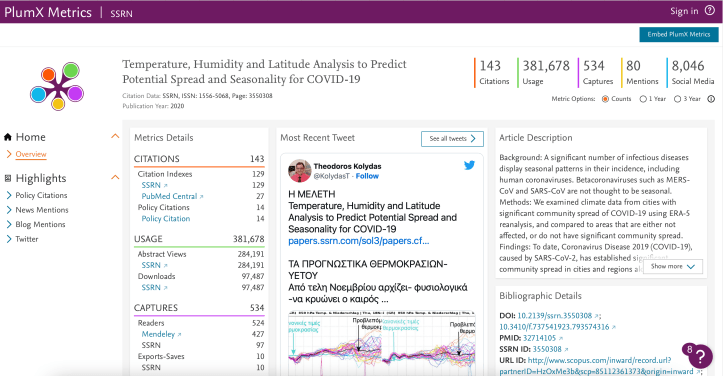
We love Plum X and we hope you do too: so make sure you click on that icon to learn more about the research you find on SSRN.
-
Tax Month on SSRN

The hot topic this month is tax! We are highlighting papers that examine a range of topics related to taxes, including tax equality, corporate taxation and tax legislation. We aim to showcase the latest papers on taxes which examine recent developments, as well as popular papers from earlier years.
This blog post lists the papers featured in March for Tax Month.
Have we missed a great paper on taxes? Let us know in the comments.
- A Study of Tax Lawyers Discussing Duties
- Do Black Taxpayers Matter? A Critical Tax Analysis of IRS Audit Practices
- Does the Tax System Favor Superstar Firms?
- Does the Impact of Tobacco Taxes Vary by Race and Gender? Taxes, Smoking, and Coronary Heart Disease Mortality in the United States, 2005-2016
- Multibillion-Dollar Tax Questions
- Pillar 2, Fiat, and the EU Unanimity Rule on Tax Matters
- Punishment Externalities and the Prison Tax
- Secure Act 2.0: A Missed Opportunity to Enhance Retirement Equity
- There Must Be Fifty Ways to Tax a Digital Nomad: Does Taxation Constrain the Geographical Freedom of the Digital Nomad?
- Tax Sanctions and the Russia-Ukraine Conflict
- The Green Bonus of Tax Incentives: Evidence from China
- The Perceived (Un)Fairness of the Global Minimum Corporate Tax Rate
- The Rise of the Robotic Tax Analyst
- To File or Not to File: Tax Compliance Among Undocumented Immigrant Workers
- Would an Unapportioned U.S. Federal Wealth Tax Be Constitutional, and What Does That Mean?
-
AI, preprints and SSRN – a new policy…

The sudden explosion of interest in AI technologies
,SSRN is thinking through issues related to this new technology: authors have submitted papers to us that have been written with the assistance of AI tools, or even written entirely by AI. We’ve had some discussions about this and in response have articulated our AI policy and we hope to provide a clear framework for authors looking for guidance on the best way to incorporate AI into their research. This policy is in line with Elsevier’s Publishing Ethics for Editors Policy.
As a preprint repository SSRN is at the cutting edge of academic research and so has become a part of the conversation about new AI technologies. SSRN recently created an AI & GPT-3 Special Topic Hub to feature the many interesting papers on this topic and to give researchers easy access to the latest thinking on how best to use AI technology. According to Shirley Decker-Lucke, Content Director at SSRN, “SSRN is a space for cutting edge thinkers to work through and share their research in all disciplines, and that of course includes the rapidly evolving area of Generative AI“.
“Our new FAQ offers our current thinking and guidelines on key aspects of authorship and this technology in the hopes that it will provide a framework for scholars who are grappling with Generative AI, how to use it, and its potential positive and negative implications,” said Decker-Lucke.
According to the new guidelines, authors should only use AI technologies to improve the readability and language of their work and not to replace key researcher or author tasks. These tasks include producing insights or theories, analysing and interpreting data, drawing conclusions, and presenting viewpoints.
Applying AI technologies should be done with human oversight and control. Authors should carefully review and edit the output generated by AI technologies since they can produce authoritative-sounding output that can be incorrect, incomplete, or biased. Authors are ultimately responsible and accountable for the contents of their work.
In accordance with our commitment to greater transparency, SSRN requires that authors provide a disclosure statement within the paper detailing any use of AI technologies. Authors should not list AI and AI technologies as an author, nor should they cite AI as an author. These measures encourage research integrity and aim to uphold ethical standards. As always, SSRN reserves the right to remove papers that do not meet its content policies or violate standards of publication ethics and research integrity.
SSRN welcomes the development of new technologies and looks forward to exploring this new wave of innovation while maintaining high levels of research integrity and clear guidance to authors, readers, contributors, and partners.
-
Meet the Author: Professor Gans on Monopolies and AI

We’re excited to present the next instalment of our author spotlight series, featuring Professor Joshua Gans. Professor Gans is currently a Professor of Strategic Management and holder of the Jeffrey S. Skoll Chair of Technical Innovation and Entrepreneurship at the Rotman School of Management at the University of Toronto (with a cross-appointment in the Department of Economics). Joshua is also Chief Economist of the University of Toronto’s Creative Destruction Lab.
Professor Gans has worked on a swathe of topic including monopolies and the impact of AI, and since we’ve been focusing on both of those subjects for the last two months, we were delighted to check in with him.
Q. We really enjoyed the book you co-authored on AI as a tool that helps to lower the cost of prediction. Have you seen recent developments in AI that have surprised you? Azeem Azaar wrote recently in his newsletter that the biggest input he has replaced in his business using AI tools is grad students…
I think there are implications in a few places as we’ve somehow hit an AI moment, and it’s quite interesting. A lot of the fanfare and the detractors of AI come from a misconception of what AI really is. As soon as you use AI with the idea that you’re talking with an intelligent entity then it’s you trying to evaluate how intelligent they are. That’s a bad way to approach it. You have to understand that you’ll only be talking to an entity that is trying to predict what response you would like to see. If you have a two hour conversation with ChatGPT and in the end it tells you it loves you, and wants to pursue a relationship with you, it’s not actually because it loves you. It’s because the conversation has gone in a direction that mirrors literature all over the world. You know, there are plenty of examples where the end response to this trope would be, “I love you.” If you can make the dialogue trope-ey enough, you can tap into a consistent set of expectations. People hate to talk about AI as being just a much better autocorrect, but that’s what it is. It’s trying to respond in a way what makes the most sense.
The amazing thing is how valuable autocorrect is! The idea that you can replace a whole load of tasks that graduate students can do is extraordinary – it’s just completely fascinating. There’s a difference between the people who write about AI in the New York Times, and everyone else who is now using it for other stuff. And for the ones who are using it for other stuff, the main danger they face is that the AI output still requires review. For example, I saw a case recently in which someone used AI to write a condolence letter, and people noticed an error which they presumably just didn’t check for. Where’s the problem there? What’s the condolence letter supposed to be? It’s not giving instructions, it’s just a template. Maybe the offensive thing here is that you spent twenty minutes to write it using AI, not an hour on your own. But for most of stuff that we do, it’s great to spend less time on it if you can. I didn’t read a lot of University admin emails before AI, so if they use AI, that will save time and who cares about the difference? We have to ask ourselves, for example with situations such as academics thinking about their students exams; if AI can answer an exam question to a good degree, was that a really good exam question, or was that some hurdle you designed to get students to pay minimal attention in a lecture? AI may pass a medical exam, but it can’t be doctor. The issues arising with AI are not new: we had similar issues before with calculators, with Excel. If everyone understood the message from prediction machines, they will be much more effective using AI, and panic about it much less. In my department, we were playing around with AI to see if it could it write an entire paper in twenty minutes. We tried it, and it’s not a great paper, but boy, does it look like it is. It has a proposition, which was wrong – interesting, but still wrong – and it has references. It’s even got the right format for an academic paper. Does that mean that SSRN will be flooded by plausible papers that don’t mean anything? I don’t think so. But is AI going to get some researchers started on a paper and get them set up? Yes it is. I expect people to become vastly more productive by using this new AI.
There’s a lot of interest in digital platforms such as Google, Amazon and Apple and their huge incumbency advantages. It seems that current anti-trust legislation is unable to deal with their formidable market positions. We’ve seen huge growth, for example with Google building in Search and Hosting, and Amazon in Online Retail. How do you think about Digital Markets and the challenge of monopolies and monopsonies?
I was disappointed in my fifty year old self for looking at these cases and discovering that actually our existing tools for regulation are doing just fine. Every issue you look at, such as Facebook taking over WhatsApp, could have been stopped under previous rules – but it wasn’t tried. I think there are a few things that are a problem, such as tech monopolies tending to acquire a lot of start-up firms. Anti-trust can’t currently see when there’s a pattern of acquiring smaller firms that could have become competition, or at least it hasn’t been really tested to deal with that. We may see some of that going forward. Could we go back and examine old mergers? I think that on the jurisprudence side of the law, it’s not really fair to revisit deals once they’ve gone through. Once you’ve done a thing you can’t really go back, although I’m sure there will be discussion about that. What people forget is that at the time of these cases, things are uncertain, and of course in hindsight it’s easy to see what could have been done. I think that our typical tools of antirust still do a good job, but there are broader issues that we are starting to face that we’re not sure how to deal with. It’s sometimes easier to think about some factors like more or less competition, but then their other factors like dead weight loss and measures of efficiency that interconnect are more difficult. The partial equilibrium notions like that, are they really the right measures market by market?
A lot of the time regulators have been looking at the impact of monopolies purely in terms of the lowering prices – does this monopoly mean cheaper products and services for consumers. Do you think that definition is enough, given the broader impact on and markets that monopolies can create?
What you have to remember is that sometimes there are only a few things that can be measured accurately, so price, for example, seems to capture a lot of what we care about. In actuality, we are relying on very textbook theories to tell us if something looks like it’s a bad monopoly issue, rather than something obvious which creates a bright line which triggers a process from there. The value added to discussion about monopolies is not in the straightforward cases, but instead in the difficult ones. A great example of this is what has happened with online retailing – there is discussion about online retailing and whether it is competition with offline retailing. Yet you have firms such as Walmart that were offline at first but now have a huge online presence. It’s just difficult! The biggest variable is how motivated the regulators are to write good antitrust laws. You can see the difference in the European regulators compared to the US: the EU regulators were very concerned with cell phone data prices and as a result plans are much cheaper than when compared with the US. The legal frameworks are there – but you have to be willing to use them. The US enforcers used to be very worried about losing in court, although they seem to be less worried about that now. From an economics point of view, the main role of antitrust is not to fight cases, but to stop companies from making the antitrust violation in the first place because their lawyers are advising them against it. The role isn’t to see them court – it’s to prevent them getting there in the first place.
I have a very specific question for you: do you think Search is a natural monopoly?
I have to declare an interest on that one, given some work I’m doing at the moment, so it’s hard to to comment, but just to say, as usual, here’s one dimension of antirust that we struggle on. Is search a monopoly? Absolutely. The issue is, will that monopoly persist into the future and is Google doing things now that are making that more likely that it will persist? That is a more difficult question. On the one hand there is a feeling that an intervention should be made now if we’re worrying about these things, but at the same time to intervene now could turn out to be the wrong thing. You might stop Google doing a whole bunch of things, but then you might also stop other competitors emerging to challenge google. But then, putting in place restrictions will send a message to other big firms. It’s confusing!
If antitrust enforcement works as it should, we should start to see a less centralised search market. For instance, academic search is not a big earner for Google, and the message for interested parties of the world should be: why do academics prefer using Google scholar? It just works better than any other options out there. Other competitors are popping up though, like Elicit. We have also seen competitors searching with ChatGPT, asking it to show all the studies with a sample size of 10,000 or more. That sort of innovation in the academic search space is very interesting.
How do you see the collision of Big Tech and AI – are we going to see a thousand AI flowers bloom, or are the well funded players such as Google, Amazon, and Apple Microsoft likely to dominate as they have in mobile and Search?
I think that AI, for reasons that historians will need to unpack, has a great start on remaining unmonopolised. Yes, all these big tech companies have AI, but most of them are providing tools to other researchers who are then building on them. There is just a lot of free flow, and that is terrific. History tells us that innovation happens and then particular complements will turn it into the next big thing, by network effects. For example, we used to worry about that in the Internet, what will be the thing that becomes important? We thought it would be landing pages – but it was actually the browser, and then it turned out to be search. These complements became very important. If I knew what the next big complement was going to be in AI, I wouldn’t be telling you, I would be getting in on the ground floor… If history is any guide, then there is some complement to AI that will rationalise everything that’s happening. We are really only a few years into this, and I don’t think we know enough about the form of AI that will emerge over time, but I don’t think GPT type things will be monopolised. But who knows? It’ll be interesting to watch.
These big companies also don’t really have a great insight into buying and exploiting new technologies. Facebook has gone for virtual reality: I’m not so sure. One of the problems is that they have the capacity to throw a lot of money at something because of the perceived threat. Microsoft did this for years, although they finally stopped that in the end. Google and Apple have done a lot of that too, as with self-driving cars. They spend a whole lot of money on the next big thing, but it turned out not quite to be there.
What role has SSRN played in your research process?
I’ve had a good run with SSRN – one year I had two of the top five downloaded papers, around the economics of the block chain. There was a huge interest in those papers, although they were very hard to publish! SSRN is huge. Back in the day when it first started, (I put up papers the week that SSRN was launched) SSRN was all about the newsletters we sent out, and we would go back and forth with those. In recent times it’s acted more as a repository, and although there are other valuable sites, I use SSRN mostly because I know how to use it and update it, and I like that I can link to it from my website.
The most attractive feature is the the number of downloads, because it’s great for academics to get anything that gives signals of value on what is important. SSRN produce rankings and everyone loves a good ranking. Google Scholar was one site where people would say that its citations aren’t as attractive as Web of Science – but in the end we all agreed we liked that we knew how to use it, and we really liked that the citation counts are a bit higher! A hundred citations on Google Scholar and two on Web of Science, that doesn’t make you feel good.
With your crystal ball, do you see big impacts big tech from recent legislation coming from either the European Union or the US? Or do you think the technical genie is well out of the regulatory bottle?
Europe has the Digital Markets Act, which is a process by which they can designate a big technology firm and change the way it deals with suppliers. As with a lot of European ‘big think’ legislation, they throw a big brush at it and it turns out it has huge unintended consequences, such as GDPR. Big companies can afford to comply, but otherwise it’s a big share of your costs for a small company to comply with it. Any legal costs to small companies really upset these markets. They are saying ‘Can we change the balance of bargaining power between small and large players…’ It will be interesting to see!
Professor Joshua Gans’ Most Recent Papers on SSRN
A Solomonic Solution to Ownership Disputes: Theory and Applications
Mechanism Design Approaches to Blockchain Consensus
-
Monopoly Month on SSRN – Part 2.

We’re rounding off Monopoly Month on SSRN, where we have been highlighting papers that examine a range of topics related to monopolies. We’ve covered a whole range of papers across the monopoly topic and we have an upcoming Meet the Author profile in line with this month’s theme.
This is the second collection of monopoly papers that we’ve featured across our social media sites in February. Some of these papers will be posted in the last few days of February. We hope you’ve enjoyed Monopoly Month!
Have we missed a great paper on monopolies? Let us know in the comments.
- AI Adoption in a Monopoly Market
- Amazon’s Trickle-Down Monopoly: Third-Party Sellers and the Transformation of Small Business
- An Antitrust Exemption for Workers: And Why Worker Bargaining Power Benefits Consumers, Too
- Antitrust and Platform Monopoly
- Democracy, Inequality, and Antitrust
- Do Antitrust Disruptors Make Good Reformers?
- Epic Games v. Apple: A Case Summary
- The Antitrust Case Against Facebook
- The Case Against Regional Transmission Monopolies
- The Economic and Social Costs of Vertical Integration by Horizontal Agreement in Minor League Baseball
- The Power of Antitrust Personhood
- Understanding Market Power
- Weak States and the Commons: Fisheries and Economic Development in the Gaspesian Peninsula circa 1830
- When Should We Look Out for the Little Guy? An Examination of the Inconsistencies in Antitrust Enforcement of Monopsony Power in Canada and the United States
- Will the Growth of Uber Increase Economic Welfare?
Have an idea for a month theme for SSRN social media? Let us know by commenting below!
-
The Launch of the AI & GPT-3 Topic Hub

SSRN is pleased to announce a new addition to the collection of Special Topic Hubs featured on its site. The AI & GPT-3 hub will feature early-stage research on generative artificial intelligence (AI), the potential applications of AI in a wide variety of fields including law, finance and education and the ongoing conversation of the ethical use of AI.
There has been an explosion of interest and research regarding advances in AI, with large language model (LLM) chatbots such as ChatGPT, Google Bard and Microsoft Bing, as well as image generation AI like DALL-E. Researchers from many disciplines are debating the role the AI will play in the coming years, how to resolve ownership of the outputs of the systems as well as setting definite guidelines to avoid misuse. The hub has been curated to include early-stage research that contributes to these topics and more, with the download count of research on the hub totalling more than 38,000.
The AI & GPT-3 Special Topic hub joins 12 other successful hubs on SSRN, which include the Coronavirus, Climate Change and Human Rights hubs. These topic hubs are all curated collections of research focusing on a specific subject of high interest in the world at the time of the launch. All 13 hubs can be found on the Special Topics Hubs landing page.
-
Monopoly Month on SSRN – Part 1.
This month we are highlighting papers that examine a range of topics related to monopolies, including their regulation, specific cases and monopoly theory. We aim to showcase the latest papers on monopolies, as well as popular papers from earlier years.
This is the first of two blog posts listing the papers featured in February for Monopoly Month.
Have we missed a great paper on monopolies? Let us know in the comments.
- Assessing Monopoly Power or Dominance in Platform Markets
- Bigger is Not Better: Preventing Monopolies in the National Cannabis Market
- Data-opolies
- Google’s (Forgotten) Monopoly – Ad Technology Services on the Open Web
- Diversification vs. Monopolization: A Laboratory Experiment
- Does Monopoly Slow Down the Bullet Train? The Impact of Market Competition on the Price of High-Speed Rail Services
- Gatekeeper Competition Policy
- Machine Learning as Natural Monopoly
- Monopolistic Behaviour and the Good Society; An Empirical Analysis of Monopoly Power and Social Good
- Monopoly without a Monopolist: An Economic Analysis of the Bitcoin Payment System
- On the Origins of the Concept of Natural Monopoly
- The 2022 Revision of China’s Anti-Monopoly Law: Global Antitrust Institute Comments on Draft Provisions of the Supreme People’s Court of the People’s Republic of China Concerning Application of the Law in Civil Disputes Arising from Monopolistic Conduct
- The Role of ‘Big Data’ in Online Platform Competition
-
Meet the Author: Professor Luciano Floridi on AI

We’re excited to present our first author spotlight blog post, featuring Professor Luciano Floridi. Professor Floridi is currently a Professor of Philosophy and Ethics of Information at the University of Oxford. He also holds a position as a Professor of Sociology of Culture and Communication at the University of Bologna.
In June, Professor Floridi will be leaving Oxford to become the Founding Director of the Digital Ethics Center at Yale University, and a Professor in the Cognitive Science program (as of late January 2023). We asked him about his new appointment, and his thoughts on the recent developments in the field of artificial intelligence, which is SSRN’s topic focus this month.
SSRN: Can you tell us about your new role as the Founding Director of the Digital Ethics Center at Yale?
Yale is investing significantly in expanding its leading role in social sciences and humanities towards STEM. As part of that wider approach, Yale has decided to invest in studying, researching, teaching, and communicating the impact of digital technologies on human life and society, the environment, and politics.
A significant investment became the creation of the new Digital Ethics Center (DEC) at Yale. I’m the lucky person who got headhunted to create the DEC and lead it. The area that we are going to cover could be described as GELSI: the Governance, Ethics, Legal, and Social Implications of digital technologies. That acronym builds on some terminology used in Brussels, but I’ve added the ‘G’ at the beginning, which is significant, because I am convinced that the governance of the digital will make a huge difference. It means deciding what to do with digital innovation.
SSRN: It seems as though the culture has suddenly become obsessed with AI, following the big breakthroughs in text to image AI (Dalle-E) and conversational AI (ChatGPT). What’s it like to find that the issues you’ve been talking about for a while have become suddenly fashionable?
On the one hand, there is a sense of relief and excitement. I have been working on these topics for decades and, with other colleagues, we saw these issues coming when no one really cared – we were just a small group of academics, you could go to a conference in the 80s and 90s on so-called “computer ethics”, but it was not at the centre of our culture, or even of the mainstream academic debates. Now, these issues have become mature and current, of interest to anyone who has had any interaction with digital technologies. This digital revolution is affecting billions of people. I’m delighted. On the other hand, there is also some frustration that we didn’t make the right decisions at the right time, when it would have been less costly. Philosophers are used to being ignored, but it still hurts. It’s just like the classic dentist’s advice: if we had brushed and flossed at the right time, we would have had fewer problems. For example, consider the Cambridge Analytica scandal and its political impact. We could have avoided that. Brexit, Trump – we are talking about significant damage to our democracies and societies which perhaps we could have minimised, if not avoided, dealing with privacy, fake news, content moderation, and other issues at an earlier stage. However, I look forward to what we can do to improve things now. There are plenty of opportunities available to us in social interactions, and in developing good legislation. I am not the usual philosopher who sees things only going from bad to worse. What good can we use these technologies for? We have two huge issues we need to tackle urgently: climate change and social inequality. Both could benefit from better use of AI, for example, and of the data we are accumulating. To put it simply, we need a good ethical framework to ensure that the bad stuff doesn’t happen, or happens less frequently, and the good stuff does, at least more frequently. There is a lot of work to be done! And we need some of the best intellects to do it.
SSRN: There’s a number of fascinating ethical challenges thrown up this new wave of AI. When AIs are being trained on copyrighted work it feels like there is a tension between protecting the copyright of existing artists and stifling innovation?
With novelty comes excitement for the new opportunities, but also its counterpart, uncertainty, and fear of what may be happening or go wrong. One mistake we should avoid is thinking that good solutions from the past can simply be used to cope with the future. Copyright has done its job, more or less well in the age of printed books, and recorded music, but increasingly we’ve seen that it’s less and less fit for purpose. The discussion about music online, streaming, buying a single song rather than an album – how do you reward the artist? We need new tools for these new features of our society.
Rather than considering how we can stretch existing solutions developed for an analogue world, we should think afresh, and see what new solutions are needed for this new digital reality. With a metaphor, we do not need to abandon or rewrite the chapter of past solutions, we need to add a new chapter. For example, if a commercial AI content production system has been trained on the paintings of a museum, something may need to be done to reward that museum…we need new forms of contracts to understand what a fair way of handling resources and profits is.
I just got a note last week from a publisher saying approximately this, in a more legal vocabulary: “Here are the new rules involving AI: if you’ve used an AI to generate even part of your paper, it has to be declared, and it can’t be listed as an author, because an AI has no legal responsibility.” Authorship means responsibility – so software cannot be an author. Wrong data in a medical journal means a real serious responsibility, for example. So, we are already adapting our context, in this case, our legal responsibilities, in the face of this new technology. We are going to see a lot of novelties in terms of the ethical, legal, and social perspectives to which we’re going to have to adapt. We have to match the novelty of the technology with the conceptual innovation in the conceptual frameworks we use to think about it and regulate it. Some time ago, I suggested to the European Commission that we should have a beta testing framework for legal uses of AI, for example. You beta test a piece of technology, so you should be able to beta test a piece of corresponding legislation, for example, in a particular city or region, as a sandbox. I’m very happy to see that this is now something they are considering.
I really enjoyed your paper on AI and Accountability, and it made me think of the news that CNET’s AI legal bot had been accused of plagiarism – quite elegantly – of other articles in the personal finance space. What do you think of this?
This form of plagiarism is going to be harder to spot, but we are also going to see something that already happened in other contexts. There has been a lot of mediocre content for a long time, you get it for free for a reason, and sometimes it’s worth very little. You get what you pay for, formulaic novels that can be churned out by the kilo, and mediocre content of all types, including movies, songs, writing, or elevator music. Think of some soundtracks for some movies – they can sound completely generic. Mass-produced things are a great step forward – we can all afford mass-produced shoes, not handmade ones. We are now seeing the mass production, on an industrial scale, of content. So many jobs we thought were irreplaceable are going to go out of the window. Let me give you an example. There used to be a job as a translator for instructions for gadgets, but that disappeared a long time ago. Yet someone able to translate Shakespeare into Italian will still be irreplaceable. And new jobs will appear because we have to manage all this. I call them green collars. I recently got involved with the first comic book entirely drawn by an AI, called “Abolition Of Man”. I know it took a special cartoonist like Carson Grubaugh to create such a unique book. In general, these new tools require unprecedented skills, abilities, imagination, aesthetic visions and so forth.
You’ve said previously that private organisations feel obliged to present themselves as green these days. Do you see a similarity in regard to AI, that organisations will need present themselves as ethical in their use of AI for commercial and reputational reasons?
As more and more legalisation is coming, a bit like the green movement, at some point, fines and compliance will come in. Yet, increasingly, it’s also no longer just what is required for compliance. In the same way that being green means much more than complying with local laws, compliance with digital legislation will be necessary but not sufficient for competitive advantage. You will have to show you are doing much more than what the law asks. If you look at some digital companies and their policies about energy consumption and carbon neutrality, I expect something similar to happen in the digital context. Companies will increasingly feel the pressure to go beyond mere compliance.
It took decades for green legislation to make a difference, it took a new culture, new rules, and new people coming into power. As the demographic profile changes, there’s more pressure and new legislation. Of course, I hope this will happen more quickly – both environmentally and digitally. I would like to see improvements happen more radically and much more quickly. There’s not much time left for either – bad digital governance can really inflict damage – disinformation and fake news cost lives during Covid-19. We need to change page much more quickly. But have we learned? I am not quite sure. One of the tasks of the new centre at Yale will be to push to get this done more quickly – we can’t wait another thirty years.
I actually believe climate change and digital change are part of the same challenge. The two worlds have become one. We do not live online or offline, we live ‘onlife’ – neither on nor offline, but both in digital and analogue realities. That’s the experience we have…more and more people increasingly live in one, seamless world. We can cope with all this by building a new alliance between the ‘green’ of all our habitats, natural and artificial, and the ‘blue’ of all our digital technologies. This is something that I cover in my forthcoming book, called The Green and The Blue – Naïve Ideas to Improve Politics in the Information Society. I believe this should be the human project for the 21st century. We need to bring environmental and digital solutions together to save both. We have a single experience of the world – we have one world to save.
What role do preprints play in your work? I can see you have over 230 papers on SSRN – how has it become part of your approach to research?
Preprints are the way forward for actual dissemination and growth of knowledge. Published research behind paywalls cannot be accessed by many people, and it’s rigid, once you have published something it can hardly be changed. The pre-print has that 21st-century quality of being flexible, you can re-upload a new file anytime, download and transform, comment on and change. You can build new relationships with preprints with other people interested in the same topics, so in terms of growth of knowledge, it’s more agile and more dynamic and more in line with the pace of knowledge creation these days. You still need the printed material because that is a record and that has other kinds of advantages, a permanent presence, for example, almost like a blockchain, but that’s more about history than the experience of knowledge work today.
I’ve always been a big fan of SSRN. Whenever we finish an article with my research group, we put it on SSRN. I recommend SSRN to all my students as the right place for them to share their research. There are other places where you can post preprints online, but for me the only platform that has a real reputation for added value is SSRN. I only wish the interface to upload papers were more intuitive!
I enjoyed your paper on Tragedy and Catastrophe. It almost made me think we should pray for a Catastrophe in order to prevent a Greater Tragedy…it’s appalling to imagine, but if we lost a major city such as Miami to climate disaster, do you think the world would wake up?
I’m afraid so. It’s the ABC of every conspiracy movie: some good people do something evil to make sure that it becomes possible to cope with something even more evil. More seriously, there is not enough proaction, you can read that piece as a prediction. I’m afraid we will not take significant action until a city such as Miami is underwater. The moment the sea goes up, the Maldives will disappear. Will that be enough? Like many people, I am worried. The hope is that Nature’s slap on humanity’s face, what I call the catastrophe, will not be too violent and yet sufficient to change direction. Perhaps we could use some rhetoric, and start linking all disasters to climate change, to ensure that humanity will take it seriously. I won’t blame politicians for playing that card. We must get the world moving in a different direction. The current one is leading to a tragedy.
Professor Luciano Floridi’s Most Recent Papers on SSRN
Using Twitter to Detect Polling Place Issues on U.S. Election Days
The Doctrine of Double Effect & Lethal Autonomous Weapon Systems
Climate Change and the Terrible Hope
The Ethics of Online Controlled Experiments (A/B testing)
The Blueprint for an AI Bill of Rights: In Search of Enaction, at Risk of Inaction
Professor Luciano Floridi on SSRN
Professor Luciano Floridi is on Twitter at @floridi
-
SSRN Uses DOI for Preprint Articles

SSRN is currently experimenting with assigning Preprint DOIs to selected papers on SSRN.
DOIs are Digital Object Identifiers assigned to each new published paper that appears in any journal. DOIs are permanent IDs that always lead to the same result, making it easy to find, link and cite published articles. DOIs are managed by Crossref, a not-for-profit membership organisation.
Currently, most articles on SSRN are assigned a generic DOI in the same way most academic journal DOIs are minted. In fact, SSRN was one of the first non-publisher entities to be allowed to mint DOIs.
Late last year SSRN began testing a new preprint DOI on a small subgroup of papers – those being published via our First Look journal partnerships.
These new preprint DOIs identify a paper as a preprint, and enable some additional metadata fields which allows the preprint to be more easily linked to any later published version.
This is an exciting development for preprint articles and for SSRN. Preprint DOIs can be used to help label preprints as a step on the way to publication in a peer-reviewed article, and means they can be more easily linked to the article’s version of record (VoR). This will help SSRN’s users to keep up to date with academic research and its progression.
What kind of DOI do you think makes sense for your research? Let us know in the comments below, and we look forward to sharing more information on our preprint DOI pilot as the experiment progresses.
You can learn more about DOIs at Crossref, which manages the technology and standards to enable DOIs to be assigned.
-
Paper Spotlight: How SSRN Can Increase Citations

This week we’re highlighting a second paper that reviews the benefits of using SSRN. In SSRN’s Impact on Citations to Legal Scholarship and How to Maximize It, Rob Willey and Melanie Knapp discuss how the number of citations per paper can be increased by distribution on SSRN.
Knapp and Willey examine a range of factors that contribute to the number of citations on papers, including paper length, length of title and whether the paper had been distributed on SSRN.
The researchers found that 87% of the most cited published papers (papers with at least 24 citations) had also been posted as preprints to SSRN. In stark contrast, only 46% of the least cited papers (three citations or less) had an SSRN version. These results indicated that posting to SSRN may have a beneficial effect on the final number of citations for a paper.
How an author presented a paper on SSRN also seemed to have an effect on citations. The number of key words selected, the abstract length and the length of the time gap between posting on SSRN and publishing in a journal were all factors that seemed to have an effect on citations.
Has posting to SSRN increased the number of eyes on your paper? Tell us about the effect SSRN has on outreach.